How To Turn Data Into Data Products?
In the digital age, data is often referred to as the new oil. However, raw data, just like crude oil, has limited value until it's refined and transformed into something useful.
However, many organizations struggle with a fundamental question: how can we make sense of this overwhelming volume of data and, more importantly, how can we turn it into something meaningful and profitable?
In this comprehensive guide, we will explore the ins and outs of turning data into data products, providing you with the knowledge and tools to harness the full potential of your data assets.
The Data Transformation Roadmap
1. Understanding Your Data Landscape: The Foundation
Before embarking on the journey of creating data products, it's crucial to have a comprehensive understanding of the data at hand. This includes identifying the sources of data, its quality, relevance, and potential biases.
By comprehending your data landscape, you lay the foundation for building trustworthy and insightful data products.
2. Defining Your Data Objectives: Setting the Direction
Every data product should have a clear purpose and objective.
Whether it's improving customer experiences, optimizing operational efficiency, or uncovering market trends, defining the objectives guides the entire process.
Ask yourself: What problem will this data product solve? How will it benefit the end-users?
These objectives will guide your decisions throughout the process.
3. Data Collection and Preprocessing: The Building Blocks
Raw data often needs refining before it can be transformed into a valuable product.
To simply put, "Think of data as puzzle pieces. You need to gather all the pieces before you can see the complete picture."
This process involves:
- Data Sourcing: Determine where and how to obtain the data you need. This might include internal databases, external sources, or data acquisition through APIs.
- Data Cleaning: Ensure the data is accurate and reliable by cleaning and preprocessing it. This step often includes handling missing values, outliers, and data inconsistencies.
- Data Storage: Choose an appropriate data storage solution that aligns with your product's requirements. Options include databases, data warehouses, or cloud-based storage services.
This step ensures that the data used for product creation is accurate and reliable.
4. Applying Advanced Analytics and Machine Learning
To extract meaningful insights from data, advanced analytics and machine learning techniques come into play. Through visualization and statistical analysis, we uncover patterns, trends, and anomalies that can drive decision-making and insights. Businesses can unveil hidden opportunities and make informed decisions.
5. Crafting the Data Product
With insights in hand, it's time to craft the data product itself.
Whether it's a predictive analytics tool, a personalized recommendation system, or a data-driven dashboard, the design phase is where the magic happens.
The key is to present the information in a way that is easily consumable and actionable for the intended audience.
6. Incorporating Human Touch and Interpretation
While data-driven insights are invaluable, adding a human touch is equally essential. Contextualizing the findings and providing interpretive narratives help bridge the gap between raw data and real-world applications. This step enhances the credibility of the data product and makes it more relatable to users.
7. Driving Engagement and Adoption
Even the most valuable data product is ineffective if it goes unnoticed. Implementing strategies to drive user engagement and adoption is crucial. This could involve training sessions, user-friendly interfaces, and ongoing support to ensure that users can effectively utilize the product to meet their needs.
Challenges in Creating Data Products
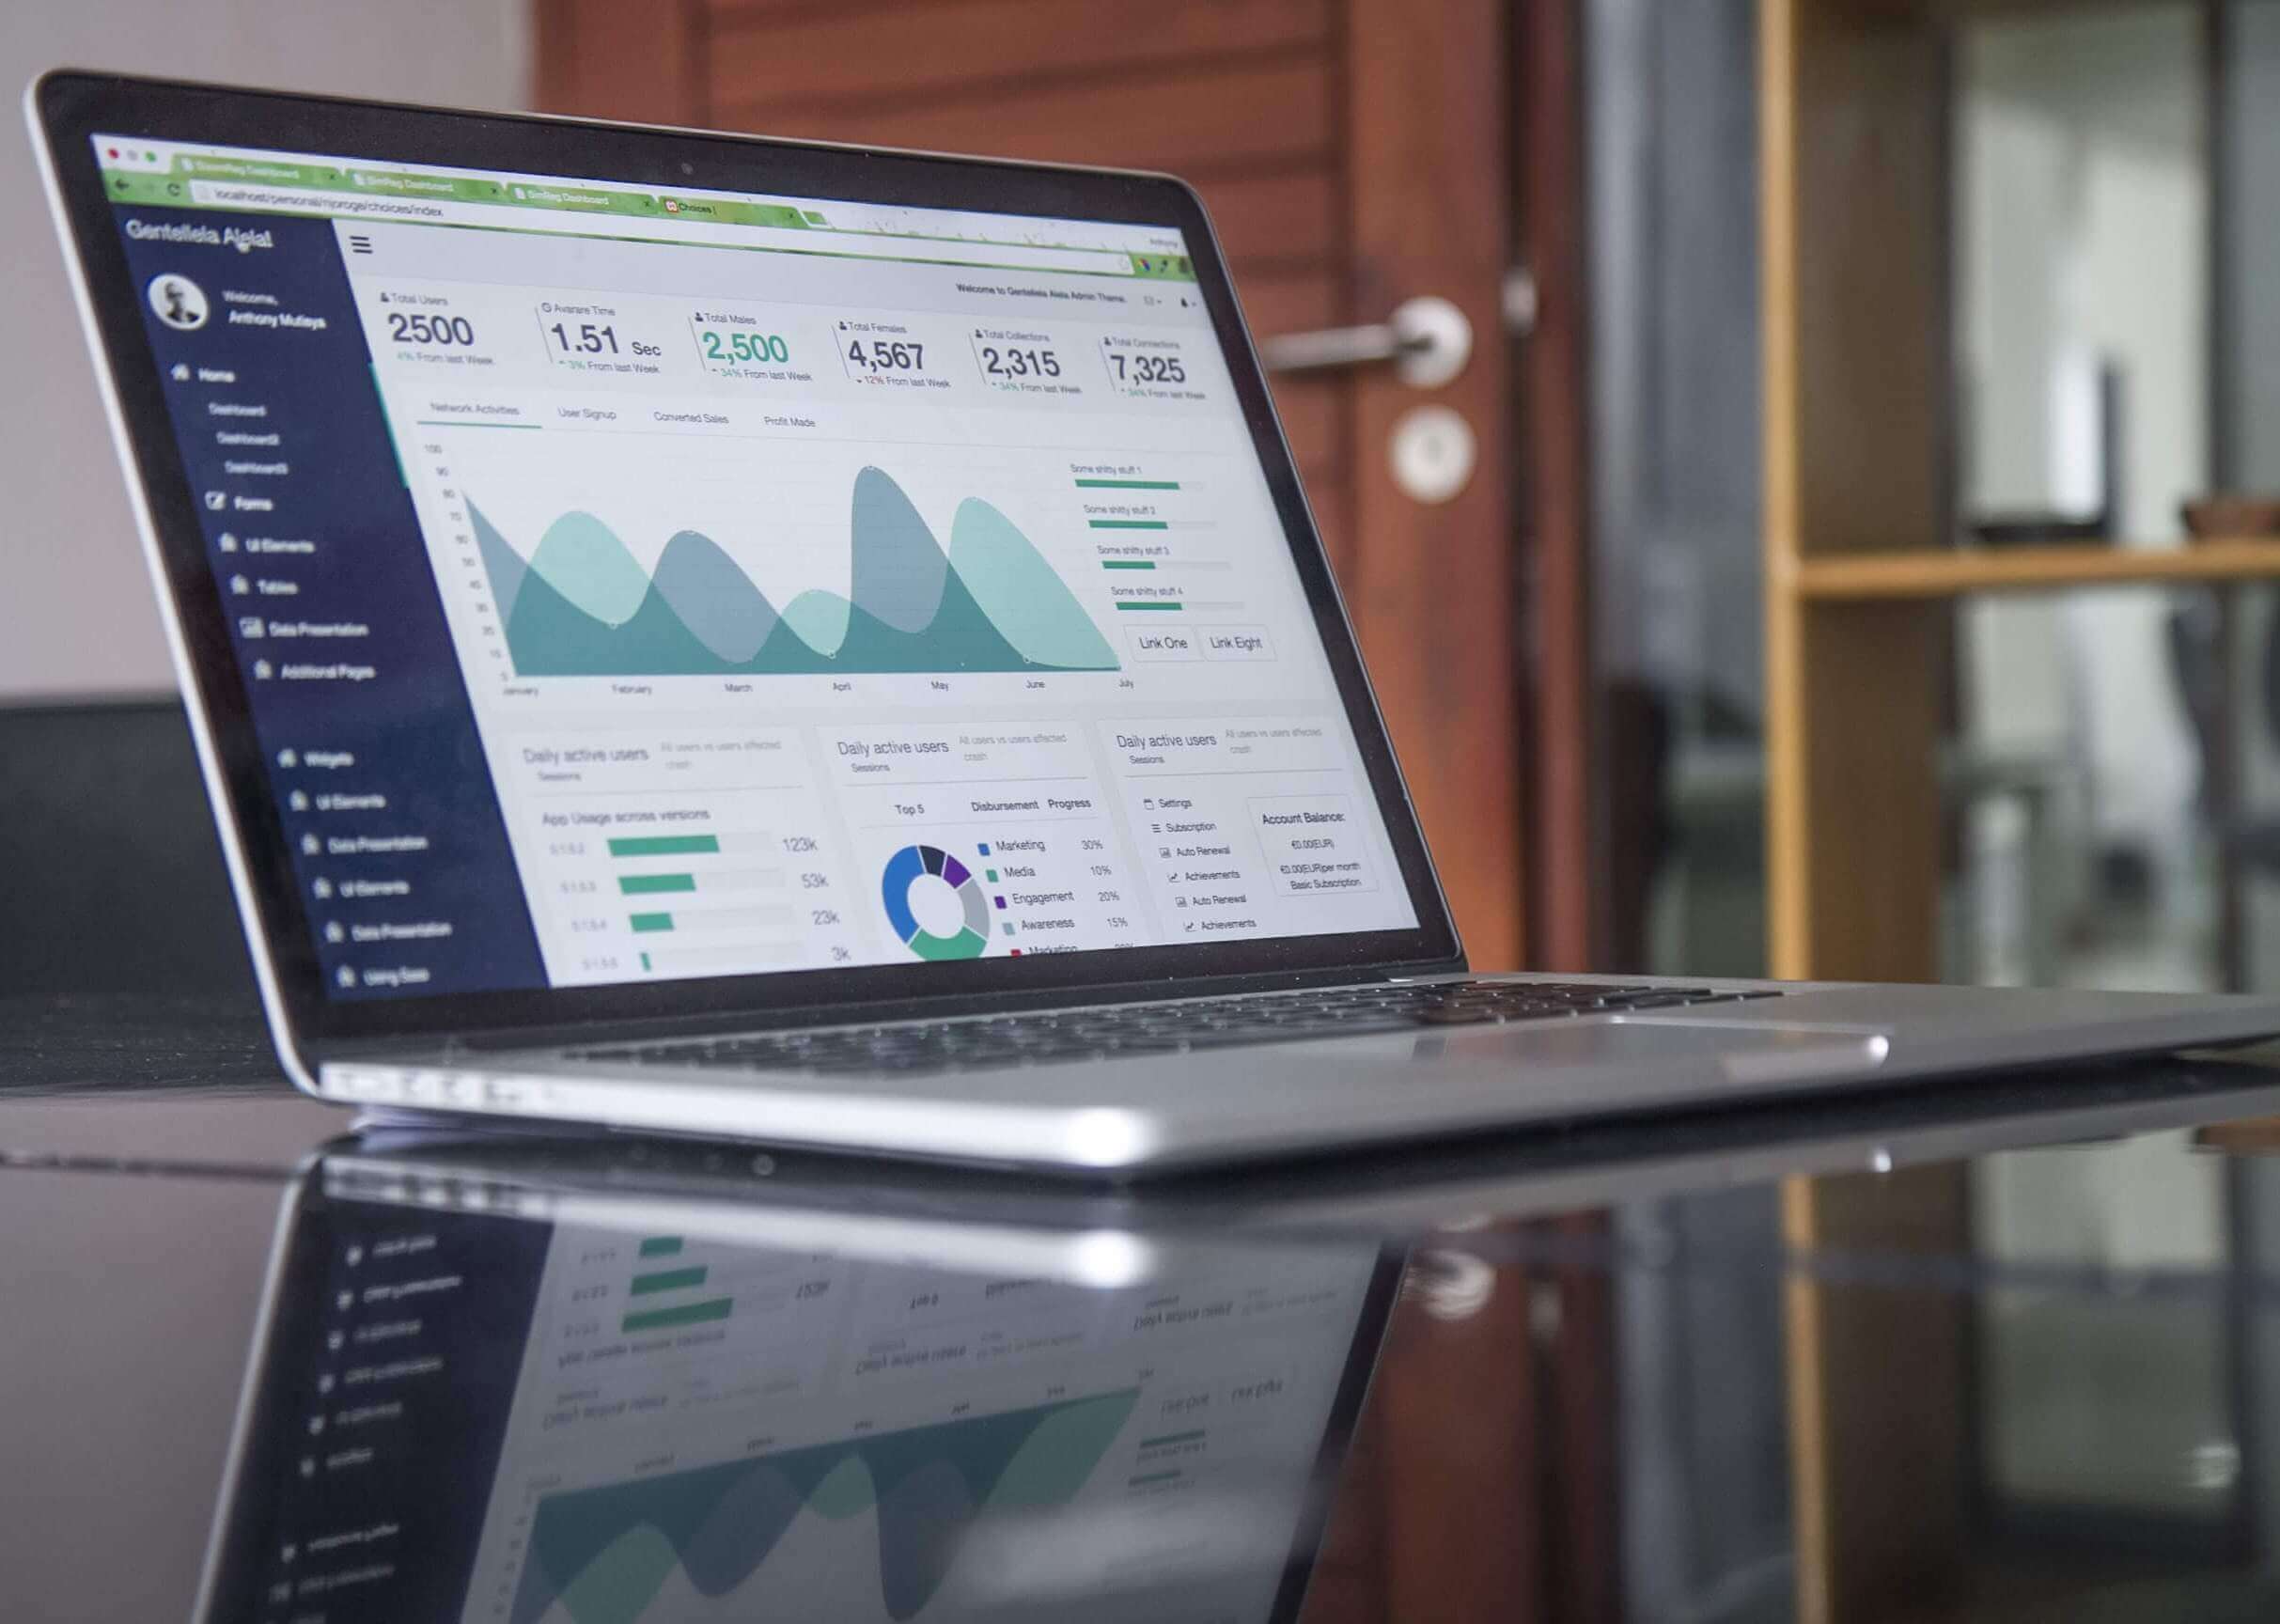
Creating data products can be challenging due to various factors. Here are some common challenges and how to address them:
Data Quality and Consistency
Challenge: Inaccurate or inconsistent data can lead to unreliable results.
Solution: Data quality is the bedrock of any successful data product. Poor data quality can result in skewed insights, incorrect predictions, and flawed decision-making.
To ensure data quality and consistency, consider the following insights:
- Data Validation and Cleaning: Implement a systematic process for data validation and cleaning. This involves identifying and addressing issues such as missing values, duplicates, outliers, and data format discrepancies. Automated data cleansing tools and scripts can significantly expedite this process.
- Data Governance: Establish a robust data governance framework within your organization. Clearly define data ownership, data stewardship roles, and data quality standards. Regularly audit and monitor data quality to ensure continuous improvement.
- Data Profiling: Use data profiling tools to gain a deeper understanding of your data. Profiling helps uncover hidden data issues and anomalies that might not be apparent during initial data collection.
Model Interpretability
Challenge: Understanding and explaining how a model makes decisions is crucial, especially in regulated industries.
Solution: Model interpretability is becoming increasingly important, not only for regulatory compliance but also for building trust and acceptance of AI-driven data products.
Here are valuable insights on tackling this challenge:
- Interpretable Models: Choose machine learning models that are inherently interpretable, such as linear regression, decision trees, or logistic regression. These models are more straightforward to explain to stakeholders.
- Feature Importance: Utilize techniques to highlight the importance of specific features in your model's decisions. Methods like feature importance scores or SHAP (SHapley Additive explanations) values can provide valuable insights into how different variables impact predictions.
- Model Explainability Tools: Leverage specialized tools and libraries designed for model interpretability, such as LIME (Local Interpretable Model-agnostic Explanations) or SHAP. These tools can generate post-hoc explanations for complex models like deep neural networks.
Privacy and Security
Challenge: Protecting sensitive data is paramount, and data products must adhere to privacy regulations.
Solution: Privacy and security concerns are critical in the age of data breaches and increasing data protection regulations.
Here are insights to safeguard your data products:
- Data Encryption: Implement strong data encryption mechanisms to protect data both at rest and in transit. Encryption ensures that even if unauthorized access occurs, the data remains unreadable.. Explore Pryzm.
- Access Controls: Implement strict access controls and permissions to limit data access to authorized personnel only. Role-based access control (RBAC) is an effective way to manage user permissions.
- Compliance Measures: Stay informed about data privacy regulations relevant to your industry, such as GDPR (General Data Protection Regulation) or HIPAA (Health Insurance Portability and Accountability Act). Ensure your data products comply with these regulations, including obtaining necessary consents and anonymizing or pseudonymizing data when required.
- Data Masking: Consider data masking techniques to replace sensitive information with fictitious data in non-production environments. This helps prevent data exposure during development and testing.
Scalability
Challenge: As data volumes and user loads grow, the infrastructure must scale accordingly.
Solution: Scalability is crucial to accommodate the growth of data and users without sacrificing performance or reliability.
Here are insights on addressing this challenge:
- Cloud-Based Services: Embrace cloud-based services, such as Amazon Web Services (AWS), Microsoft Azure, or Google Cloud Platform (GCP). These platforms offer scalable resources that can automatically adjust to meet demand, reducing the burden of infrastructure planning. Explore Smart Credit.
- Microservices Architecture: Consider adopting a microservices architecture for your data products. This approach breaks down the application into smaller, independent components that can be scaled individually, allowing for better resource allocation.
- Load Balancing: Implement load balancing techniques to distribute incoming traffic evenly across multiple servers or instances. Load balancers ensure that no single component becomes a bottleneck, thus improving scalability and fault tolerance.
- Horizontal Scaling: Focus on horizontal scaling, which involves adding more instances or nodes to your system to handle increased load. This approach is often more cost-effective and efficient than vertical scaling (increasing the power of a single server).
The Conclusion: From Data to Value
Turning data into data products is not just a technical process; it's a strategic endeavor that can redefine the way your business operates. By following the roadmap outlined above, you can harness the full potential of your data, gaining insights that drive innovation and competitive advantage.
In the age of data, those who can transform information into actionable intelligence are the ones who will lead the way. So, ask yourself, "How can I turn my data into products that change the game?" The answer might just be the key to your organization's future success.